Aman Nandhra

Home

Hey, I’m Aman.

I build analytics workflows, forecasting models, and applications that turn data into useful tools.

I’m a UC Berkeley graduate with a B.A. in Data Science and an emphasis in cognition. I work with Python, SQL, and visualization tools to investigate problems, test ideas, and communicate findings.

View Projects View Resume

Selected Work

  • Inventory Analytics: Identified $523K in excess inventory through a SQL, Python, and Power BI workflow.
  • Traffic Forecasting: Reduced hourly forecasting error by about 49% compared with an hour and weekday baseline.
  • Resume Matching: Built a Chrome extension that evaluates job requirements against resume evidence.

Let’s Connect

I’m seeking opportunities in data analytics and data engineering where I can build reliable workflows and help teams make informed decisions.

GitHub (opens in a new tab) LinkedIn (opens in a new tab) Email

Projects

Statistical modeling, predictive analytics, and software development — from understanding the data to building and evaluating a solution.

Resume Job Matching Chrome Extension

Apr 2026 · Python, JavaScript, NLP, LLMs

Overview

An AI-driven Chrome extension that automates resume–job matching. It evaluates how well a resume fits a job description directly in the browser, using semantic understanding, structured requirement extraction, and evidence-based scoring rather than keyword counts.

Methodology

  • Designed a modular scoring pipeline that combines structured similarity signals with LLM outputs to rank job fit and provide repeatable recommendations.
  • Scores each posting on three parts — eligibility (minimum requirements), relevance (how closely experience aligns) and evidence (proof of similar work) — and combines them into an overall match score.
  • Runs on job boards such as HiringCafe, parsing job descriptions automatically and showing results in the page.

Results

  • A working, user-facing extension that integrates NLP, similarity scoring, and LLM prompt workflows.
  • A feedback loop from marked applications evaluates outcomes and iteratively refines recommendation quality, creating a foundation for continuous model and prompt improvement.

Traffic Volume Demand Forecasting and Capacity Analysis

Jul 2025 · Python, ML

Overview

An end-to-end machine learning workflow forecasting hourly traffic volume on westbound I-94 near Minneapolis–St. Paul, using about 48,000 hourly observations from 2012 to 2018, to forecast demand and analyze system behavior under changing load.

Methodology

  • Cleaned the data: duplicate timestamps, a 10-month sensor gap, impossible temperature and rainfall readings, and a road-resurfacing anomaly.
  • Engineered temporal, weather, and traffic lag features (1 hour, 24 hours, 1 week).
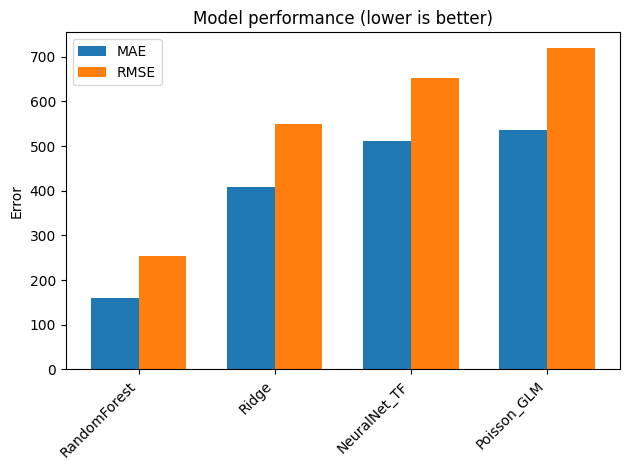
  • Benchmarked Ridge Regression, Poisson GLM, Random Forest, XGBoost, and a stacked ensemble against lookup-table and persistence baselines, using MAE, RMSE, and time-series cross-validation.
  • Enforced forecast-issue-time cut-offs at every fold so no model trains on outcomes it could not have seen.

Results

  • One-hour-ahead model: MAE 153 vehicles/hour, R² 0.986 — about half the error of the hour-by-weekday lookup table (MAE 300).
  • Rolling 24-hour-ahead model: MAE 253 vehicles/hour, R² 0.945.
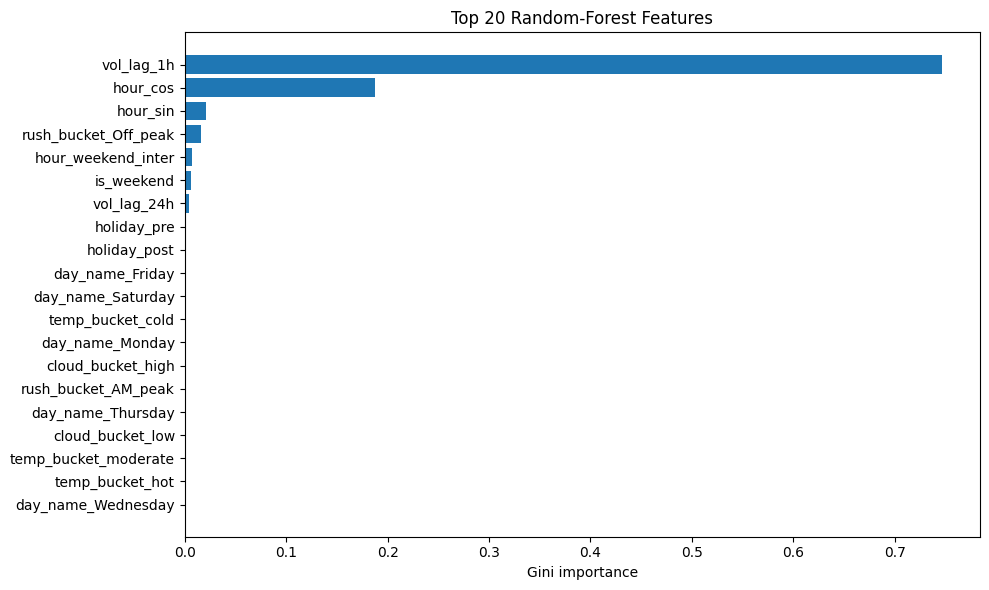
  • Time of day and recent traffic history were the strongest predictors; weather added under 2%, so the models don’t depend on a weather forecast.
  • Turned the experimentation into a repeatable forecasting workflow.

Inventory Analytics and Optimization

Jul 2026 · Python, SQL, Power BI

Overview

An end-to-end analytics pipeline (SQL → Python → Power BI) over 91,250 records across 50 SKUs, 5 warehouses, and 10 suppliers, analyzing inventory, demand, supplier lead times, and replenishment risk.

Methodology

  • Audited the raw data, loaded it into a normalized SQLite database, and cleaned and validated it with quality checks throughout the workflow.
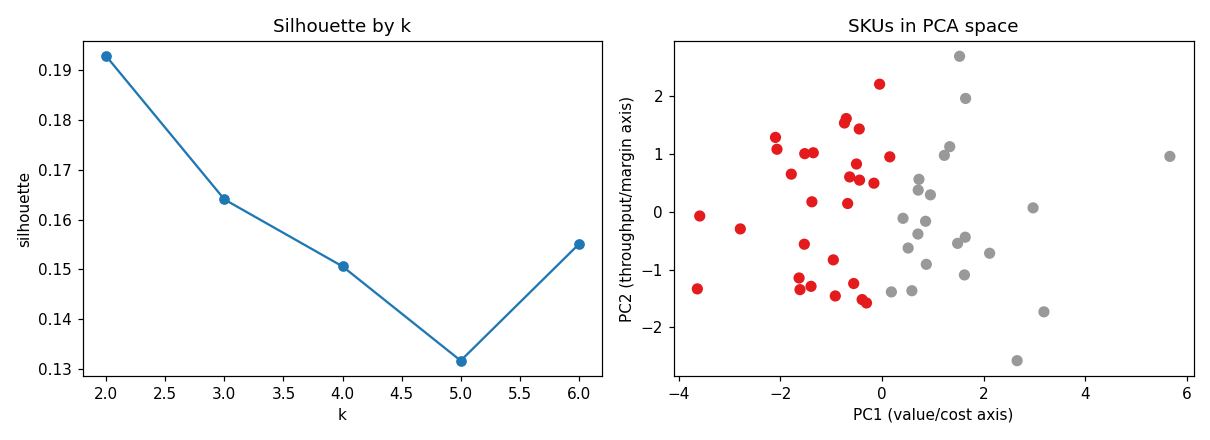
  • Applied statistical segmentation and K-Means clustering to group SKUs by value and throughput.
  • Evaluated cost–service tradeoffs between 95% and 99% availability targets and summarized the findings in a stakeholder dashboard.

Results

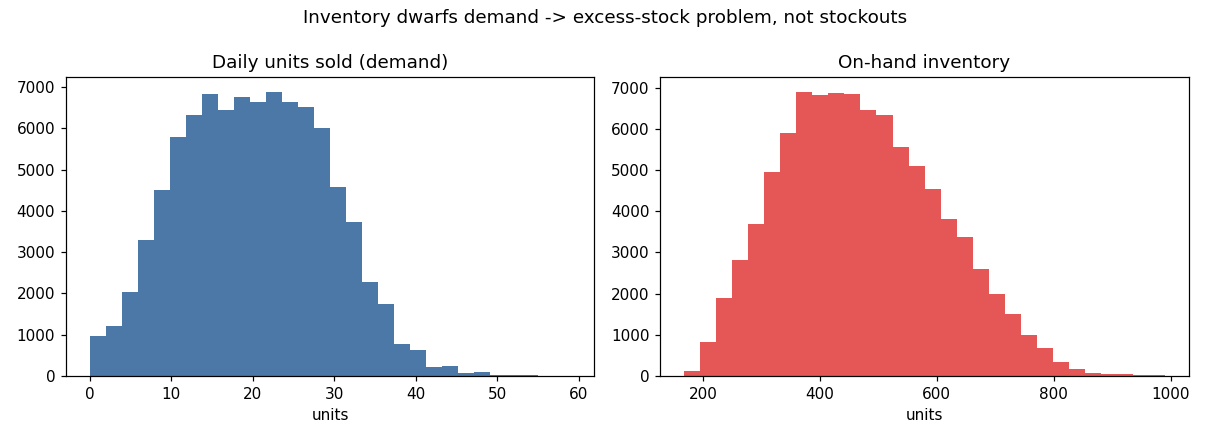
  • Identified $523K in persistent excess inventory above the reorder point.
  • Quantified the cost of raising service levels from 95% to 99% availability.
  • Traced the overstock to static, conservative replenishment parameters.

NBA Player Performance Analysis

Apr 2026 · Python, Power BI, Data Visualization

Overview

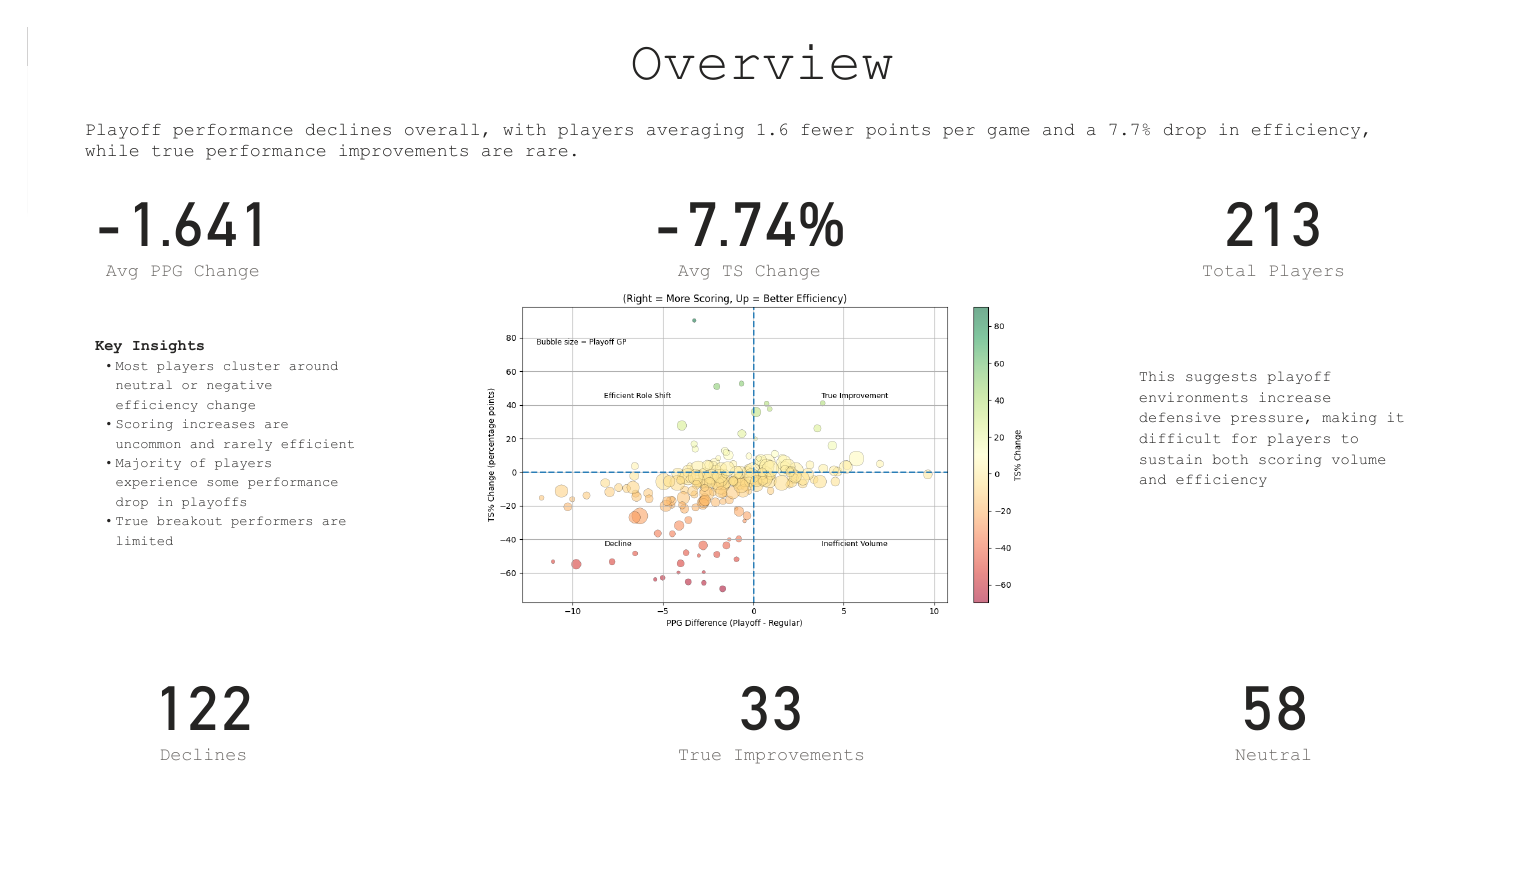
An analysis of how player scoring and efficiency change from the regular season to the playoffs, where defensive intensity and game planning rise sharply.

Methodology

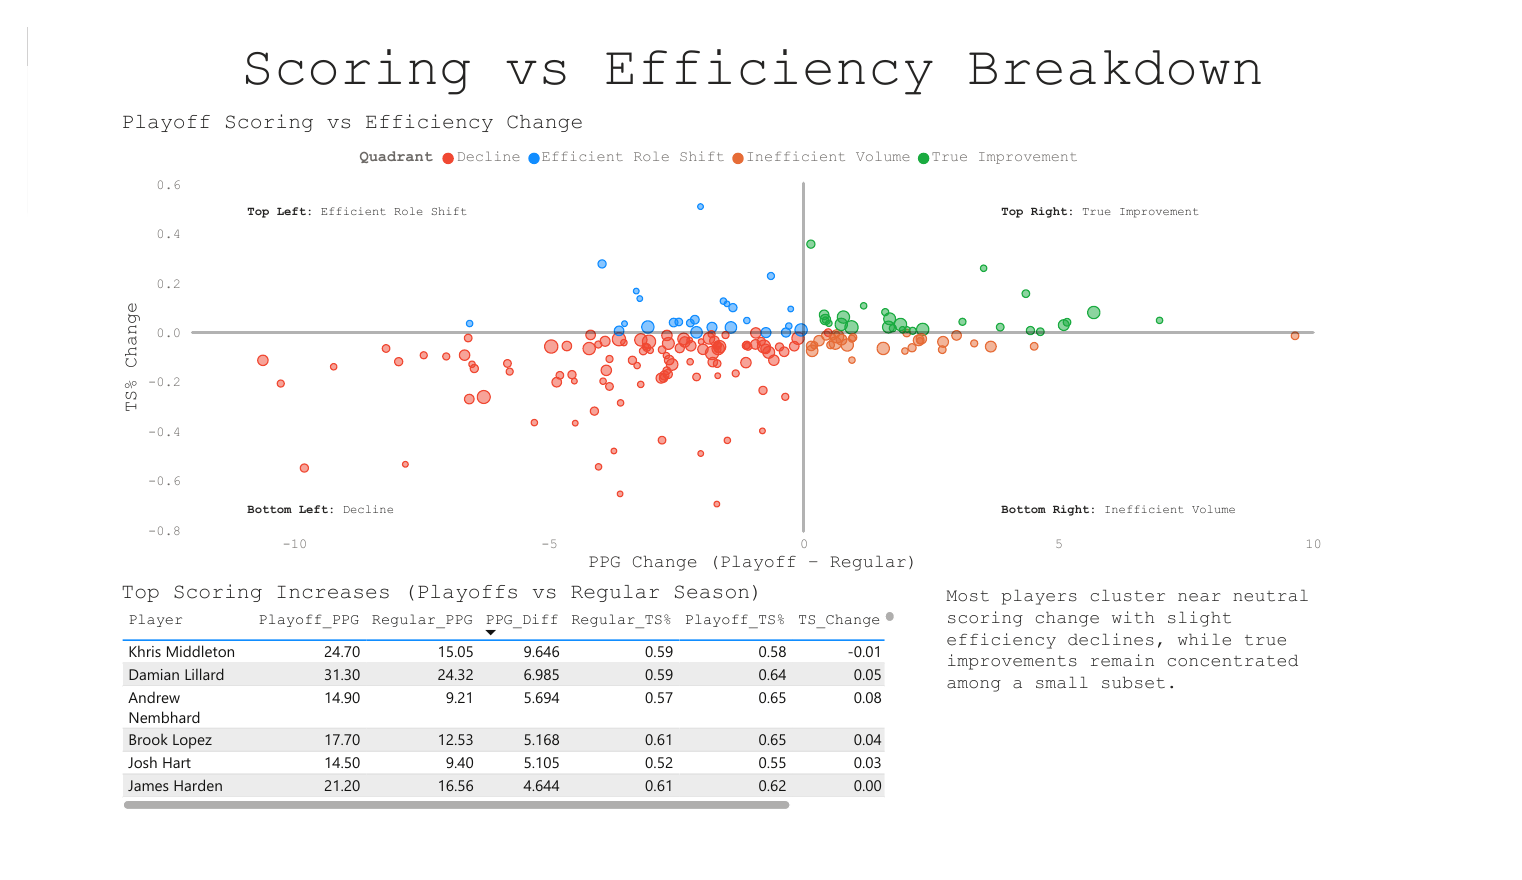
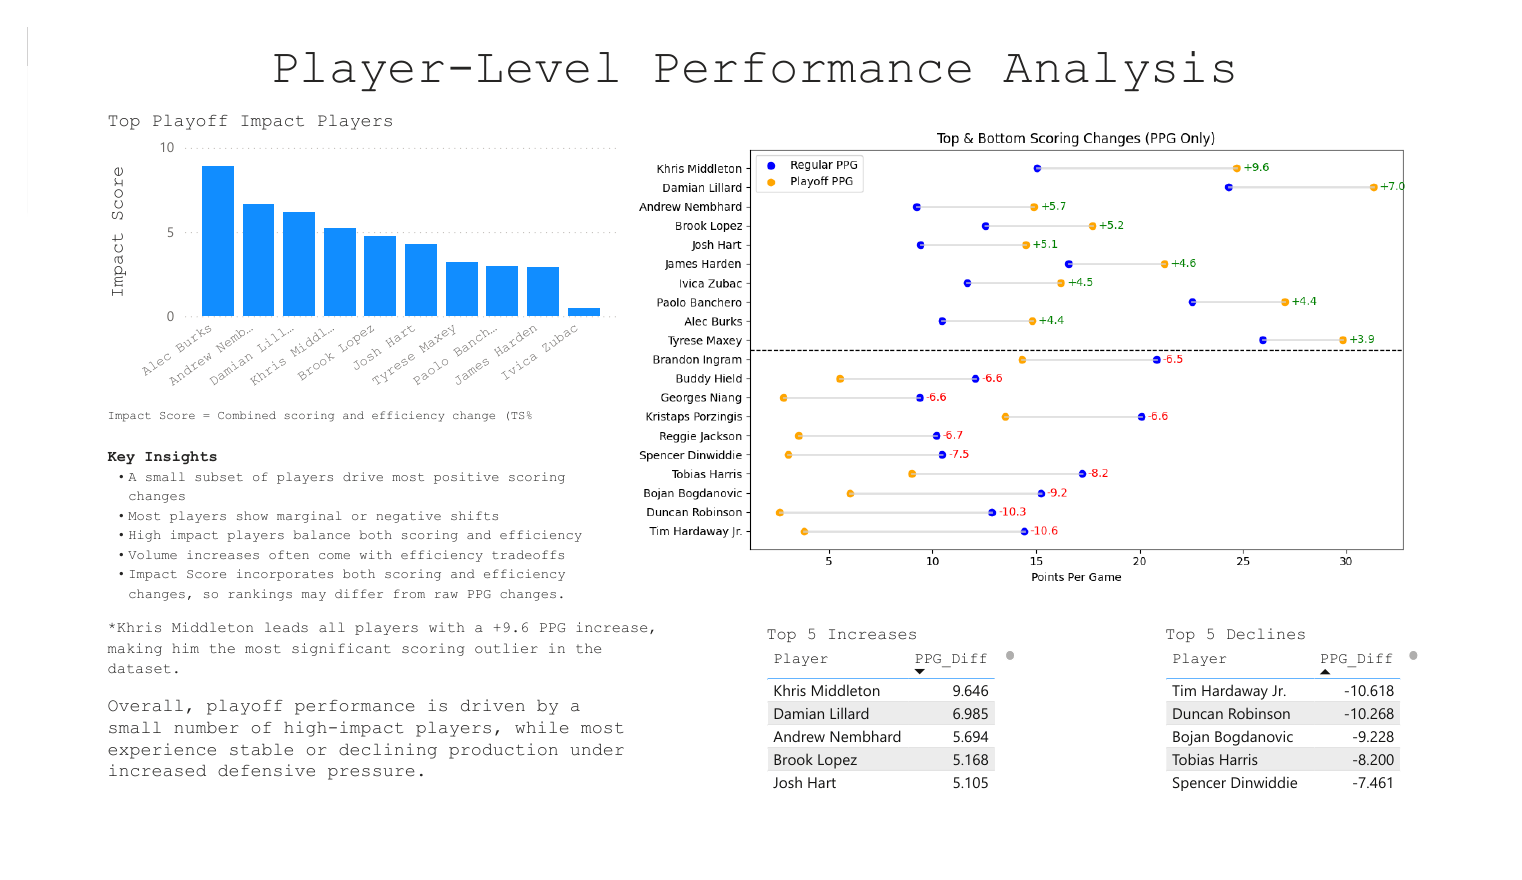
  • Engineered performance deltas for scoring (PPG) and efficiency (TS%), plus an impact score combining both.
  • Grouped players into four quadrants: true improvement, efficient role shift, inefficient volume, and decline.
  • Built Python-based visualizations and a multi-page interactive Power BI dashboard (with DAX measures) to surface player-level patterns.

Results

  • Over 57% of players saw efficiency decline in the playoffs.
  • Across 213 players, scoring fell by about 1.6 points per game and true shooting by 7.7% on average; only 33 improved in both scoring and efficiency.

Currently Building

Work in progress: what works today and what’s next.

TFT AI Coach

In progress Python · Riot API · DuckDB

RIOT CONNECTION

Authentication     PASS
Account lookup     PASS
Match list         PASS
Match retrieval    PASS
Raw JSON saved     PASS

Riot API ready.
Sample result: the API connection check, as printed by riot_smoke_test.py.
Problem

Coaching advice for Teamfight Tactics is only as good as the data behind it. This project builds a coach on a clean, trustworthy dataset of what top-ladder players actually do, collected and validated from Riot’s API.

Working now
  • Riot API gateway with shard routing, rate limits adopted from Riot’s headers, retries for 429/5xx/timeouts, and clear error types.
  • High-Elo collection: Challenger and Grandmaster ladders → top players → their recent matches, de-duplicated, with resumable runs and an untouched raw archive.
  • Normalized database (DuckDB + Parquet): seven tables from matches to items and augments, each match validated and inserted atomically, with integrity checks.
Next milestone

Patch knowledge: mapping Riot’s internal unit, item and trait IDs to display names for each patch, ahead of the analytics, model and coach stages.

About

Beyond Data and Code

My experience spans live event technology, student government communications, and creative leadership. I enjoy understanding how things work, helping people solve problems, and bringing ideas to life.

A/V and Event Technology

With the Berkeley Orchestra A/V team, I helped set up microphones, cameras, audio equipment, and livestreams. I checked radios and communications equipment and adapted setups to different events and spaces.

ASUC Communications

At ASUC, I helped create campaign posts and share what student government was working on. I turned activities and updates into content that helped students understand what was happening and how to get involved.

Innovative Design

As VP of Internal at Innovative Design, I organized events for a club of more than 100 members and led a team of seven. I coordinated planning and responsibilities to bring members together and support the club’s activities.

Personal Interests

I built my own PC and upgrade it as my needs change. I also help friends troubleshoot their systems and enjoy figuring out what’s causing a problem.

I produce and mix music, experimenting with sound design, arrangement, and how the elements of a track fit together. One goal I’m working toward is opening at Bill Graham Civic Auditorium for an artist like Crankdat or Kai Wachi.

Resume

Download PDF LinkedIn GitHub Email

Experience

Operations AnalystJul 2025 – Sep 2025

731 LLCRemote

  • Collected and integrated large-scale real estate data from MLS (Multiple Listing Service) and public listing platforms into a unified dataset, maintaining consistent inputs for downstream analysis.
  • Developed repeatable data processing workflows to validate, organize, and filter listings against client criteria, reducing manual screening and improving workflow reliability.
  • Improved lead identification through data-driven screening and analysis, enabling approximately 50% faster client outreach and reduced time-to-match.
  • Partnered with business stakeholders to translate requirements and analytical findings into practical workflow improvements and recurring reporting.

Education

University of California, BerkeleyMay 2024

B.A. in Data ScienceBerkeley, CA

Relevant coursework: Data Structures, Probability and Statistics, Data Mining, Data Inference, Econometrics, Optimization, Machine Learning.

Projects

  • Resume Job Matching Chrome Extension Apr 2026 · Python, JavaScript, NLP, LLMs
  • Traffic Volume Demand Forecasting and Capacity Analysis Jul 2025 · Python, ML
  • Inventory Analytics and Optimization Jul 2026 · Python, SQL, Power BI
  • NBA Player Performance Analysis Apr 2026 · Python, Power BI, Data Visualization

See project details

Technical Skills

Languages
Python, Java, SQL, C++, R, JavaScript
Machine Learning & AI
TensorFlow, Scikit-learn, NLP, LLM Prompt Workflows, Similarity Scoring, Model Evaluation, Feature Engineering
Software & Data Engineering
Git, REST APIs, ETL Pipelines, Workflow Automation, Data Validation, Data Modeling
Data Libraries
Pandas, NumPy, Matplotlib
Systems
Relational Databases (Postgres, SQLite), Cloud Fundamentals (AWS), Unix Basics
Analytics
Statistics, Algorithms, A/B Testing, Power BI (DAX), Tableau, Excel